Insights, Networking, and innovation
Lorem ipsum dolor sit amet, consectetur adipiscing elit, sed do eiusmod tempor incididunt ut labore
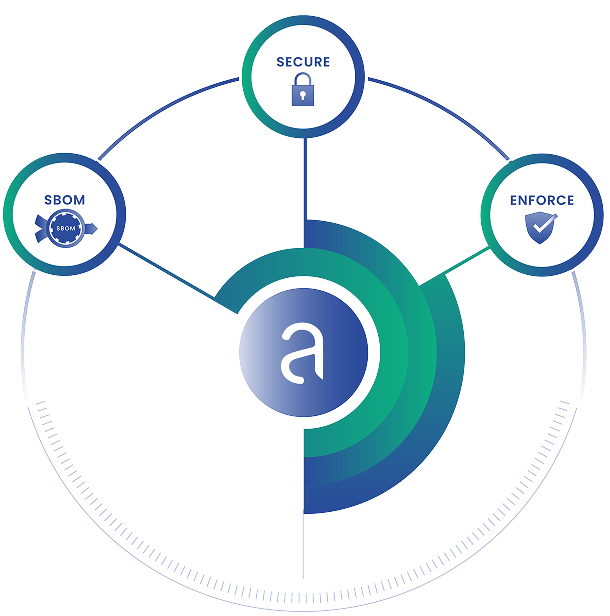
Open source AI models are landing in production software the same way open source libraries did a decade ago fast, broadly, and largely untracked. Teams pulling models from Hugging Face or similar repositories often have limited visibility into license obligations, provenance, or known vulnerabilities. And unlike a standard open source package, most SBOMs don't account for them at all.
Regulators are closing that gap: organizations cannot meet compliance requirements unless they track AI models with the same rigor applied to open source components which means accurate inventory, vulnerability correlation, and inclusion in your SBOM output.
In this webinar, we cover what it takes to bring open source AI models under the same governance framework you apply to the rest of your software supply chain:
 Christopher Phillips Senior Software Engineer, Anchore |
 Dan Nurmi Chief Research Officer, Anchore |